Quick start
Try it in a minute
Section titled “Try it in a minute”Once you have installed indice you can index a sample WACZ file into a new collection.
wget https://github.com/edsu/indice/raw/refs/heads/main/apod.waczindice index --collection "APOD" apod.waczindice serveOpen http://127.0.0.1:8080 and you should see the new collection, and be able to replay:
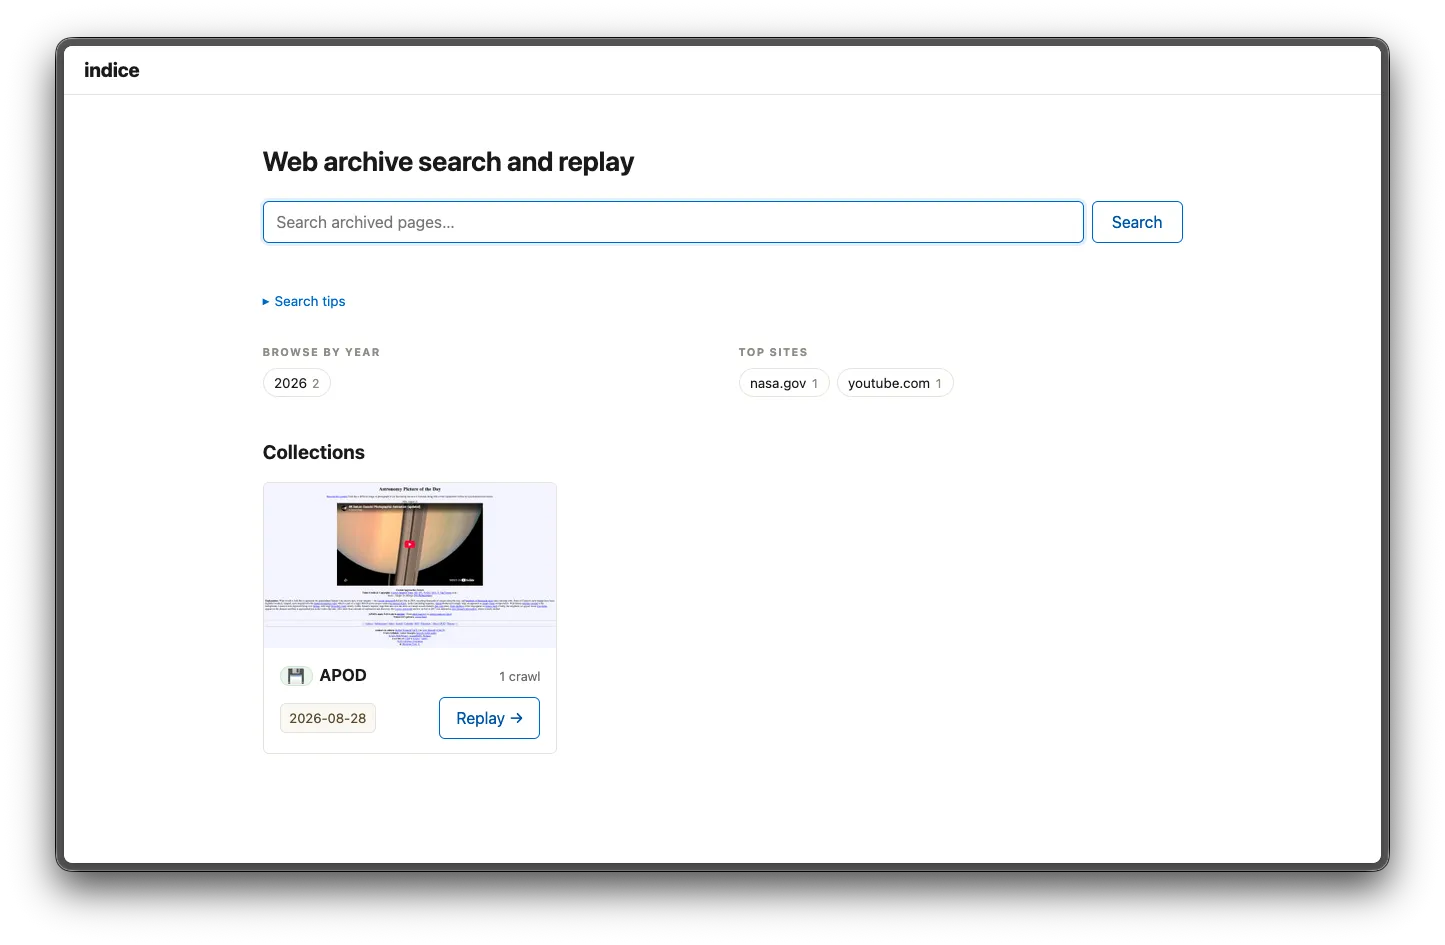
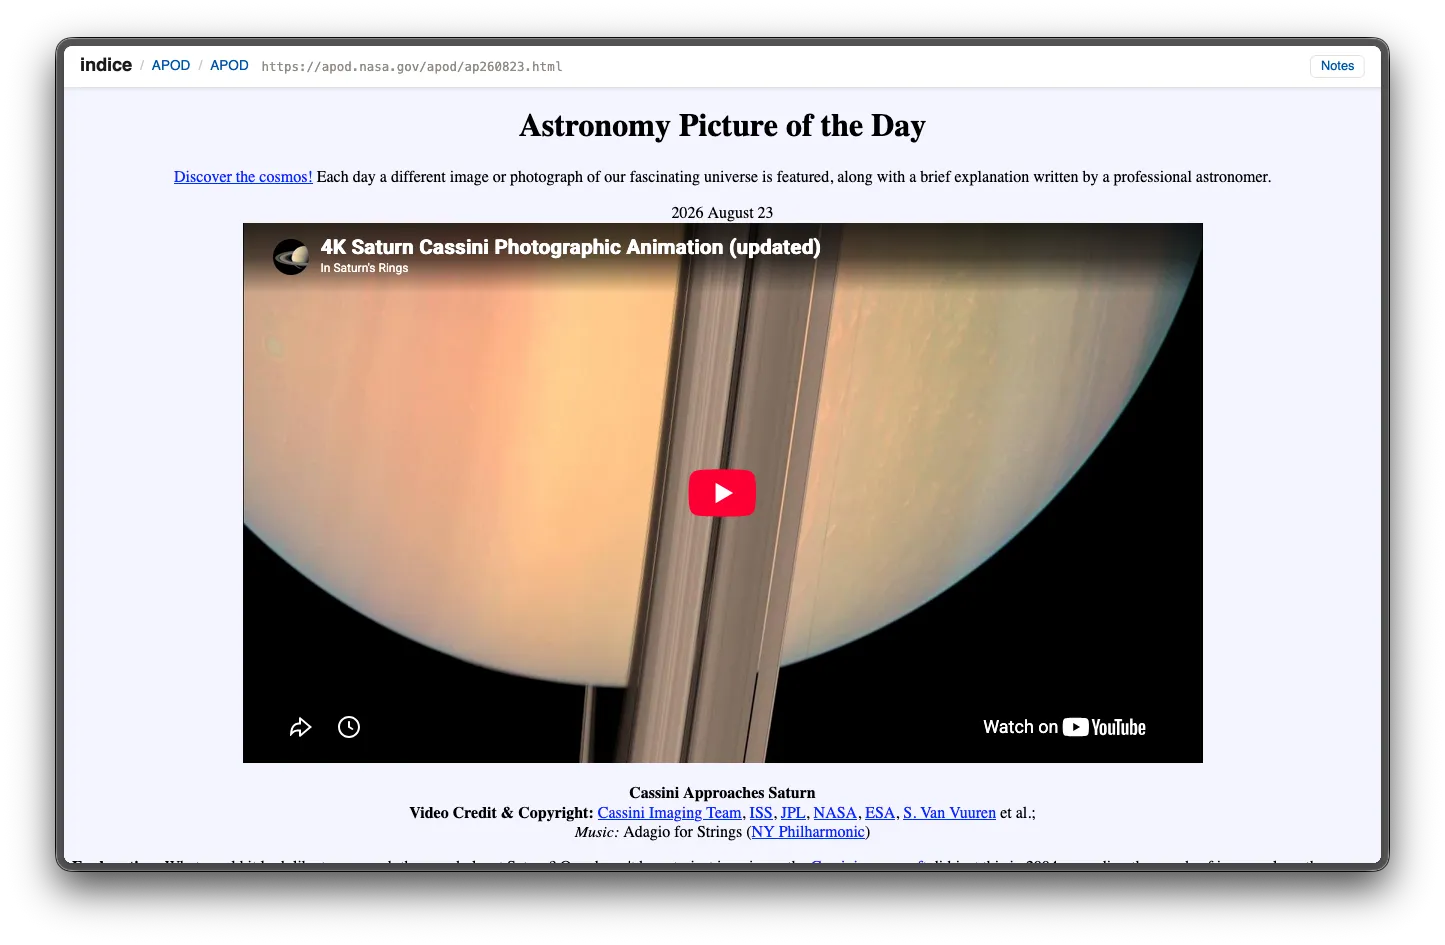
Point indice index at your own .wacz files the same way (local paths or http(s):// URLs); indice serve also gives you an in-browser interface for adding and curating crawls. To learn more see Manage & curate.
The home directory
Section titled “The home directory”indice keeps everything under a home directory (default: the current directory):
<home>/├── archive/<slug>/ your WACZ files, organized by collection├── collections/<slug>/ finding aids you author + commit (README.md, thumbnails, notes)└── index/ search index + derived metadata (rebuildable; git-ignore it)If you want, the collections/ folder might be worth keeping in version control, since it contains the prose and images a curator writes, and annotations. index/ is derived from the WACZs and rebuilt by indice reindex, so a home in git typically .gitignores /index. See The home directory for the full layout, what to version-control, and how backup works.
Index and serve
Section titled “Index and serve”Index one or more WACZ files into a collection, then serve:
indice index my-archive.wacz --collection "My Web Archive" # files it into archive/my-web-archive/indice serve # http://127.0.0.1:8080serve also listens on the next port, 127.0.0.1:8081, for replay. Archived pages run their own JavaScript, and serving them from a different origin keeps that script away from your workroom. You never visit that port yourself; the viewer frames it.
Every crawl belongs to a collection, so index requires --collection <NAME> (created if new). This is deliberate, to encourage curators to say what a crawl is a part of and why it is being kept. Describe a collection further (creator, dates, rights, a scope note) with indice collection set, which writes a git-committable finding aid at collections/<slug>/README.md. You can also edit in the management interface.
A local WACZ can live anywhere, so indice index path/to/foo.wacz --collection "Bar" files it into <home>/archive/bar/ for you (moving it if it’s already under archive/, copying it otherwise, so your original is left intact). The source is stored relative to home, so you can move or copy the whole <home> directory to another disk or machine and it still works. You can point at a different “home” with --home <DIR> (every command takes it).
index takes one or more archived WACZ files or http(s) URLs, so you can also index a single file or a remote WACZ:
indice index archive/my-archive.wacz --collection "My Web Archive"indice index https://example.org/site.wacz --collection "My Web Archive"To rebuild the index later from what you’ve already indexed, use indice reindex instead of re-listing everything.
Open http://127.0.0.1:8080/, search, and click a result to replay it.
(If you built from a clone instead of installing, use ./target/debug/indice in place of indice.)
Re-running index skips sources already indexed into a collection, so a large or interrupted ingest is safe to re-run; it resumes where it left off. Pass --force to re-index (refresh) a source that’s already there.
Remote WACZ files
Section titled “Remote WACZ files”A WACZ can also live at an http(s) URL instead of being stored locally. This can be helpful in situations where there are too many WACZ files to store locally. For example, this one is hosted on S3:
indice index https://edsu-webarchives.s3.amazonaws.com/docnow.wacz --collection "DocNow"indice serveBy default indice streams a remote WACZ. It never downloads the whole file. Using the WACZ’s internal CDX index, it reads (via HTTP range requests) only the pieces it needs: the ZIP central directory, the CDX, and the HTML/PDF page records. It skips images, video, JS, and CSS entirely. On a media-heavy archive the indexable text is a tiny fraction of the WACZ: a 323 MB WACZ can be indexed in a few seconds. The URL is recorded as the source, and at replay time the browser reads the remote WACZ directly (also via range requests).
For this to work the remote host must serve the WACZ with HTTP range support and CORS allowing indice’s origin. The S3 bucket above is configured that way (Accept-Ranges: bytes and Access-Control-Allow-Origin: *), which is why S3 and other object stores work with no special support: expose the object as a range- and CORS-capable HTTPS URL (public or presigned) and index it.
If you’d rather keep a local copy, add --download:
indice index --download https://edsu-webarchives.s3.amazonaws.com/docnow.wacz --collection "DocNow"This fetches the WACZ into <home>/archive, indexes it as a local file, and records a whole-file SHA-256, a durable copy you can replay offline and check with indice verify. indice also falls back to downloading automatically if a remote host doesn’t support range requests, or if the WACZ stores its WARCs compressed (the WACZ spec says the archive/ WARCs should be stored uncompressed so they can be read by range; a few tools don’t).
Streaming a large remote WACZ makes one HTTP range request per page record. Those requests are latency-bound and independent, so indice fetches them concurrently (4 at a time by default, which is gentle on an arbitrary host; raise it, e.g. --concurrency 16, for object stores like S3). Fetches retry transient failures (rate limits and 5xx) with backoff, honoring Retry-After, so a long ingest survives blips and stays gentle on the host. Be mindful that a high --concurrency all hits a single host, so dial it down for small servers. As a backstop the worker count is capped at 64 per host, so a mis-typed value can’t flood a single server. index shows a progress bar: a spinner while it reads the CDX, then a bar with the throughput and an ETA once it knows how many records there are. Add -v/--verbose for detailed logs instead of the bar; when output isn’t a terminal (piping to a file or CI) it prints plain log lines and no bar.
For the details of how indice reads a WACZ (CDX-guided vs. full scan), see How indice works.